Complete reference for bm25vector, bm25query, tsvector, <&>, to_bm25query, bm25_page_inspect, and all 19 pg_tokenizer functions.
This is the multi-page printable view of this section. .
Reference & Benchmarks
Complete SQL reference, GUC parameters, benchmarks, and version history for vchord_bm25 and pg_tokenizer.
Complete technical reference for vchord_bm25 and pg_tokenizer:
Session GUCs and index storage parameters across v0.1–v0.3 (bm25_catalog.) and main (bm25.).
QPS and NDCG@10 accuracy comparisons against Elasticsearch, Lucene, ParadeDB, and PostgreSQL GIN.
Changelog and schema evolution from v0.1.0 through v0.3.0 to the next-generation native tsvector architecture.
1 - SQL Reference
Complete SQL data types, operators, casts, index access methods, and functions for vchord_bm25 and pg_tokenizer.
vchord_bm25 Data Types
| Data Type | Schema | Versions | Text Representation / Structure | Description |
|---|---|---|---|---|
bm25vector |
bm25_catalog |
v0.1.0 – v0.3.0 |
{token_id:freq, ...} (e.g., {1:1, 2:2, 15:1}) |
Sparse vector mapping 32-bit unsigned token IDs to 32-bit term frequencies. Stored with STORAGE = EXTERNAL. |
bm25query |
bm25_catalog |
v0.1.0 – v0.3.0 |
(index_oid regclass, query_vector bm25vector) |
Composite type pairing a target bm25 index OID with a query bm25vector. |
bm25query |
public / ext schema |
main |
(vector tsvector, index regclass) |
Composite type pairing a query tsvector with a target bm25 index OID. |
bm25vector Literal Syntax (v0.1 – v0.3)
vchord_bm25 Operators
| Operator | Left Arg | Right Arg | Return Type | Versions | Description |
|---|---|---|---|---|---|
<&> |
bm25vector |
bm25query |
real (f32) |
v0.1.0 – v0.3.0 |
Computes the negative BM25 relevance score ($-\text{BM25}(D, Q)$). Supports index-accelerated ORDER BY ... ASC scans using bm25_ops. |
<&> |
tsvector |
bm25query |
float8 (f64) |
main |
Computes the negative BM25 relevance score on native tsvector. Supports index-accelerated ORDER BY ... ASC scans using bm25_ops. |
= |
bm25vector |
bm25vector |
bool |
v0.2.0 – v0.3.0 |
Exact equality comparison between two bm25vector values. |
<> |
bm25vector |
bm25vector |
bool |
v0.2.0 – v0.3.0 |
Inequality comparison between two bm25vector values. |
vchord_bm25 Functions
| Function Signature | Return Type | Versions | Description |
|---|---|---|---|
to_bm25query(index_oid regclass, query_vector bm25vector) |
bm25query |
v0.1.1 – v0.3.0 |
Constructs a bm25query from a bm25 index name/OID and a query bm25vector (or INT[] via implicit cast). |
to_bm25query(index_oid regclass, query_vector int[]) |
bm25query |
v0.3.0+ |
Explicit overload accepting an INT[] token ID array directly. |
to_bm25query(vector tsvector, index regclass) |
bm25query |
main |
Constructs a bm25query from a native tsvector and target bm25 index name/OID. |
search_bm25query(target_vector bm25vector, query bm25query) |
real |
v0.1.0 – v0.3.0 |
Underlying implementation function for bm25vector <&> bm25query. |
_bm25_evaluate(left tsvector, right bm25query) |
float8 |
main |
Underlying implementation function for tsvector <&> bm25query. |
bm25_page_inspect(index regclass, blkno int) |
text |
v0.3.0 |
Returns human-readable diagnostic metadata for block blkno of a bm25 index. |
vchord_bm25 Access Method & Operator Class
| Object | Name | Target Type | Ordering Operator |
|---|---|---|---|
| Access Method | bm25 |
Index | Handler _bm25_amhandler |
| Operator Family | bm25_ops |
USING bm25 |
OPERATOR 1 pg_catalog.<&> FOR ORDER BY float_ops |
| Operator Class | bm25_ops |
bm25vector (v0.1–v0.3) / tsvector (main) |
Default operator class for USING bm25 |
pg_tokenizer Functions (tokenizer_catalog)
All pg_tokenizer functions reside in the tokenizer_catalog schema:
Tokenizer Management & Execution
| Function Signature | Return Type | Description |
|---|---|---|
create_tokenizer(name TEXT, config TEXT) |
void |
Creates a named tokenizer from a TOML configuration string. |
drop_tokenizer(name TEXT) |
void |
Drops an existing tokenizer. |
tokenize(text TEXT, tokenizer_name TEXT) |
INT[] |
Tokenizes text using tokenizer_name and returns an array of integer token IDs (implicitly castable to bm25vector). |
Text Analyzer Management
| Function Signature | Return Type | Description |
|---|---|---|
create_text_analyzer(name TEXT, config TEXT) |
void |
Creates a reusable named text analyzer pipeline (character_filters, pre_tokenizer, token_filters). |
drop_text_analyzer(name TEXT) |
void |
Drops a named text analyzer. |
apply_text_analyzer(text TEXT, text_analyzer_name TEXT) |
TEXT[] |
Runs a text analyzer on text and returns the array of normalized string tokens (useful for debugging). |
Model Management
| Function Signature | Return Type | Description |
|---|---|---|
create_custom_model(name TEXT, config TEXT) |
void |
Trains a custom vocabulary model on an existing table column using a text analyzer. |
drop_custom_model(name TEXT) |
void |
Drops a custom model and its backing vocabulary table. |
create_custom_model_tokenizer_and_trigger(tokenizer_name TEXT, model_name TEXT, text_analyzer_name TEXT, table_name TEXT, source_column TEXT, target_column TEXT) |
void |
Creates a custom model, creates a tokenizer, populates target_column on table_name, and attaches an automatic BEFORE INSERT OR UPDATE trigger. |
create_huggingface_model(name TEXT, config TEXT) |
void |
Imports a model from a HuggingFace tokenizer.json string. |
drop_huggingface_model(name TEXT) |
void |
Drops an imported HuggingFace model. |
create_lindera_model(name TEXT, config TEXT) |
void |
Creates a Lindera morphological analysis model (e.g., ipadic) from a TOML config. |
drop_lindera_model(name TEXT) |
void |
Drops a Lindera model. |
Dictionary & Preload Management
| Function Signature | Return Type | Description |
|---|---|---|
create_stopwords(name TEXT, config TEXT) |
void |
Creates a custom stopword dictionary (one word per line). |
drop_stopwords(name TEXT) |
void |
Drops a custom stopword dictionary. |
create_synonym(name TEXT, config TEXT) |
void |
Creates a custom synonym dictionary (space-separated synonyms per line, mapped to the first word). |
drop_synonym(name TEXT) |
void |
Drops a custom synonym dictionary. |
add_preload_model(name TEXT) |
void |
Registers a model to be preloaded at PostgreSQL server startup (shared_preload_libraries). |
remove_preload_model(name TEXT) |
void |
Removes a model from the startup preload list. |
list_preload_models() |
TEXT[] |
Returns the list of models currently registered for preloading. |
Internal Trigger & Helper Functions (tokenizer_catalog)
| Function Signature | Return Type | Description |
|---|---|---|
apply_text_analyzer_for_custom_model(text TEXT, text_analyzer_name TEXT) |
TEXT[] |
Applies text_analyzer_name and filters out tokens exceeding 2600 bytes (PostgreSQL B-tree UNIQUE index maximum key size) before inserting into a custom model vocabulary table. |
custom_model_insert_trigger() |
trigger |
AFTER INSERT OR UPDATE trigger function that extracts new tokens from the source text column and inserts unseen tokens into tokenizer_catalog."model_<name>". |
custom_model_tokenizer_set_target_column_trigger() |
trigger |
BEFORE INSERT OR UPDATE trigger function installed by create_custom_model_tokenizer_and_trigger that automatically populates NEW.<target_column> = tokenize(NEW.<source_column>, tokenizer_name). |
pg_tokenizer Catalog Tables (tokenizer_catalog)
| Table Name | Columns | Description |
|---|---|---|
tokenizer_catalog.tokenizer |
name TEXT NOT NULL UNIQUE, config TEXT NOT NULL |
Stores registered tokenizer names and their serialized JSON/TOML configuration. |
tokenizer_catalog.text_analyzer |
name TEXT NOT NULL UNIQUE, config TEXT NOT NULL |
Stores standalone reusable text analyzer definitions. |
tokenizer_catalog.model |
name TEXT NOT NULL UNIQUE, config TEXT NOT NULL |
Stores registered custom, HuggingFace, and Lindera model definitions. |
tokenizer_catalog.stopwords |
name TEXT NOT NULL PRIMARY KEY, config TEXT NOT NULL |
Stores built-in (lucene_english, nltk_english, iso_english) and custom stopword dictionaries. |
tokenizer_catalog.synonym |
name TEXT NOT NULL PRIMARY KEY, config TEXT NOT NULL |
Stores custom synonym dictionaries. |
tokenizer_catalog."model_<name>" |
id SERIAL PRIMARY KEY, token TEXT NOT NULL UNIQUE |
Backing vocabulary table created for each custom model <name>, mapping unique normalized tokens to 1-based integer IDs. |
pg_tokenizer TOML Configuration Reference
Tokenizer Options (create_tokenizer)
| Option | Type | Description |
|---|---|---|
text_analyzer |
string (optional) |
Name of a pre-created text_analyzer. If omitted, inline character_filters, pre_tokenizer, and token_filters may be defined directly (when supported by model). |
model |
string (required) |
Name of a built-in model (llmlingua2, bert_base_uncased, wiki_tocken, gemma2b) or a user-created model (custom, huggingface, or lindera). |
Text Analyzer Options (create_text_analyzer)
| Option | Type | Description |
|---|---|---|
character_filters |
array / table |
List of character filters applied to the full string before splitting: to_lowercase, unicode_normalization (nfc, nfd, nfkc, nfkd). |
pre_tokenizer |
string / table |
Single pre-tokenizer that splits the string into initial tokens: unicode_segmentation, regex (Rust regex string), or jieba (mode = "full" | "precise" | "search", enable_hmm = true | false). |
token_filters |
array |
Ordered list of token filters: skip_non_alphanumeric, stemmer (30 Snowball stemmers), stopwords (lucene_english, nltk_english, iso_english, or custom), synonym, pg_dict (any pg_ts_dict except Thesaurus), ngram (min_gram, max_gram in 1..=255, preserve_original). |
Custom Model Options (create_custom_model)
| Option | Type | Description |
|---|---|---|
table |
string (required) |
Target table name containing the source text corpus. |
column |
string (required) |
Source TEXT column name on table used to build the vocabulary. |
text_analyzer |
string (required) |
Name of the text_analyzer used to tokenize column into vocabulary terms. |
2 - GUC & Index Parameters
Complete reference of session GUC parameters and index storage options for vchord_bm25.
Stable Releases (v0.1.0 – v0.3.0): bm25_catalog.* GUCs
In versions v0.1.0 through v0.3.0, all session GUC parameters use the bm25_catalog. prefix and can be changed per session or transaction by any user (GucContext::Userset):
| Parameter Name | Type | Default | Valid Range | Description |
|---|---|---|---|---|
bm25_catalog.bm25_limit |
integer |
100 |
-1 .. 65535 |
Maximum number of top-scoring documents to return from a bm25 index scan. Set to -1 to disable Block-WeakAnd pruning and perform an exhaustive brute-force scan; set to 0 to return no rows. Must be your SQL LIMIT. |
bm25_catalog.enable_index |
boolean |
true |
true / false |
Enables or disables the bm25 index scan in the PostgreSQL query planner. Set to false to force a sequential scan with exact search_bm25query evaluation. |
bm25_catalog.enable_prefilter |
boolean |
true |
true / false |
Introduced in v0.2.2. When true, filters out documents that do not satisfy the query/visibility check before inserting them into the Block-WeakAnd Top-K heap. |
bm25_catalog.segment_growing_max_page_size |
integer |
4096 |
1 .. 1000000 |
Maximum size (in 8 KB pages, default 4096 = 32 MB) of the append-only growing segment before it is sealed into a compressed, delta-bitpacked read-only segment. |
Examples (v0.1 – v0.3)
Next-Gen main Branch: bm25.* GUCs & Index Reloptions
In the main branch rewrite, session GUCs use the bm25. prefix and work together with per-index storage parameters (WITH (...)):
Session GUC Parameters (main)
| Parameter Name | Type | Default | Valid Range | Description |
|---|---|---|---|---|
bm25.enable_scan |
boolean |
true |
true / false |
Enables or disables bm25 index scans in the planner. |
bm25.limit |
integer |
100 |
0 .. 65535 |
Maximum number of results returned by a bm25 index scan. If set to 0, falls back to the index’s limit storage parameter. |
bm25.prefilter |
boolean |
false |
true / false |
Enables pre-filtering during bm25 index scans (overrides the index’s prefilter storage parameter when true). |
Index Storage Parameters (WITH (...) in main)
| Storage Parameter | Type | Default | Valid Range | Description |
|---|---|---|---|---|
options |
string (TOML) |
k1 = 1.2, b = 0.75 |
k1: 1.2..2.0b: 0.0..1.0 |
TOML string configuring the Okapi BM25 parameters and for the index. |
limit |
integer |
0 |
0 .. 65535 |
Per-index fallback search limit used when bm25.limit = 0. |
prefilter |
boolean |
false |
true / false |
Per-index default prefilter setting. |
3 - Benchmarks
QPS throughput and NDCG@10 retrieval accuracy benchmarks for VectorChord-BM25 against Elasticsearch, Lucene, ParadeDB, and PostgreSQL GIN.
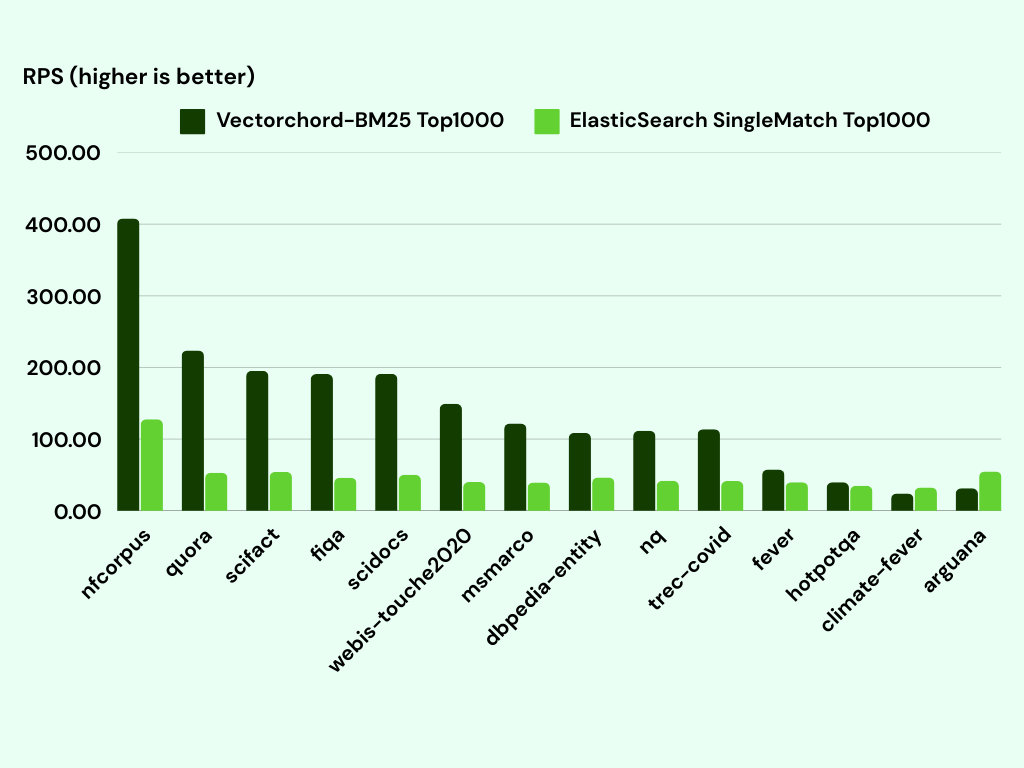
Throughput Benchmark (QPS vs. Elasticsearch, Lucene, ParadeDB, PG GIN)
VectorChord-BM25’s Block-WeakAnd implementation with 128-document delta-bitpacked blocks and 1-byte fieldnorm quantization delivers up to 3x higher QPS than Tantivy-based PostgreSQL extensions (ParadeDB / pg_search) and an order of magnitude higher QPS than native PostgreSQL GIN indexes on Top-10 ranked queries:
Why vchord_bm25 Achieves High QPS
- Zero Cross-Engine Serialization: Unlike foreign-data-wrapper or external Tantivy/Lucene bridges,
vchord_bm25stores its segments directly inside PostgreSQL buffer pages (PostgresRelation), avoiding tuple marshaling overhead. - Aggressive Block-Max Pruning: On multi-term queries, Block-WeakAnd skips over 80%–95% of 128-document posting blocks without decompressing them once the Top-10 threshold stabilizes.
- 256-Entry Precomputed BM25 Lookup Table: Quantizing document length into a 1-byte
fieldnormreplaces expensive per-document floating-point math with a single array lookup.
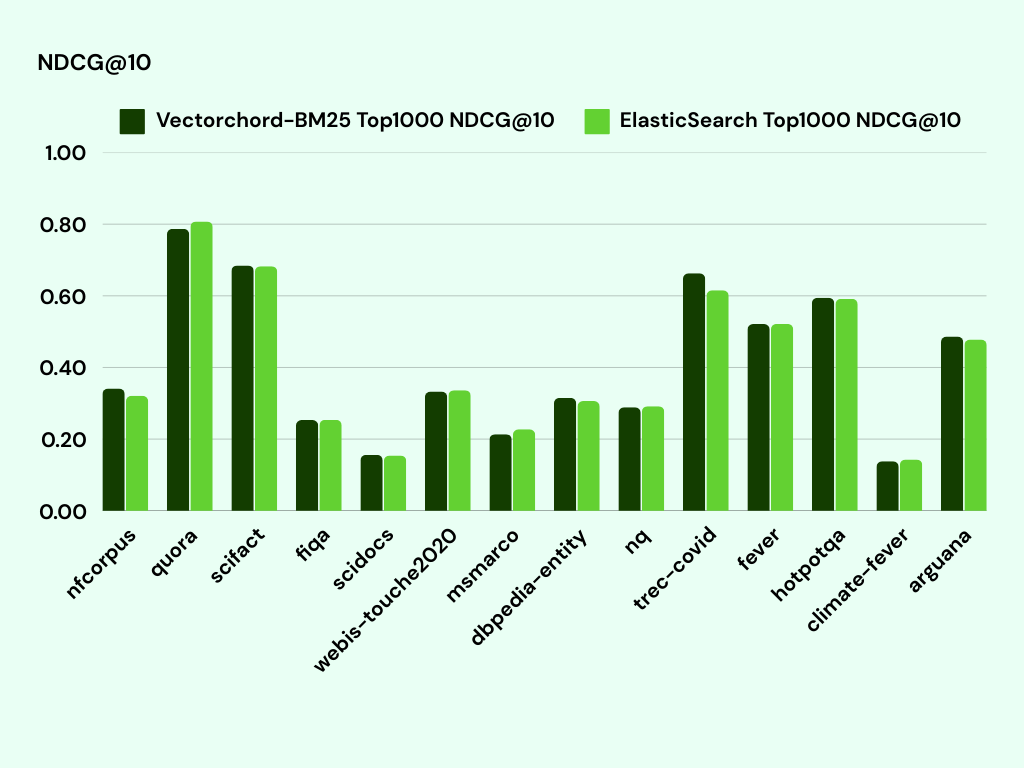
Retrieval Accuracy Benchmark (NDCG@10 on BEIR & LoTTE)
The table below (from our BEIR / LoTTE Hybrid Search & ColBERT Reranking evaluation) compares retrieval accuracy (NDCG@10) across:
- PostgreSQL
vchordDense Vector Search (Vector) - PostgreSQL
vchord_bm25Lexical Search (BM25) - Hybrid Search (
vchord+vchord_bm25with ColBERT Rerank)
| Dataset | Domain | Vector (vchord) |
BM25 (vchord_bm25) |
Hybrid + ColBERT Rerank |
|---|---|---|---|---|
| scifact | Scientific Fact-Checking | 0.676 | 0.665 | 0.751 |
| nfcorpus | Bio-Medical IR | 0.340 | 0.325 | 0.370 |
| fiqa | Financial QA | 0.405 | 0.236 | 0.415 |
| trec-covid | Biomedical COVID-19 | 0.728 | 0.656 | 0.838 |
| LoTTE-lifestyle (search) | Lifestyle QA | 0.735 | 0.635 | 0.779 |
| LoTTE-lifestyle (forum) | Lifestyle Forum | 0.662 | 0.506 | 0.701 |
| LoTTE-recreation (search) | Recreation QA | 0.642 | 0.564 | 0.708 |
| LoTTE-technology (search) | Technology QA | 0.562 | 0.483 | 0.647 |
| LoTTE-writing (search) | Writing QA | 0.726 | 0.674 | 0.793 |
Tip
Combining vchord_bm25 with vchord consistently outperforms either dense vector search or lexical BM25 alone across every evaluated dataset. See Hybrid Search (BM25 + VectorChord) for SQL query templates.
4 - Release History & API Evolution
Version changelog and SQL schema evolution of VectorChord-BM25 (vchord_bm25) from v0.1.0 to v0.3.0 and main.
This page tracks the release history and SQL schema evolution of vchord_bm25 (pgsty/vchord_bm25 / supervc-stack/VectorChord-bm25).
Version Summary Matrix
| Version | Schema | Indexed Type | Tokenizer | Key Additions |
|---|---|---|---|---|
main (Next-Gen) |
Extension schema | tsvector |
Native to_tsvector (or custom) |
Complete storage & index engine rewrite on native tsvector; external sort parallel ambuild; index reloptions (options, limit, prefilter); bm25.* GUCs; PostgreSQL 18 support. |
v0.3.0 |
bm25_catalog |
bm25vector |
pg_tokenizer |
Added bm25_page_inspect(regclass, int), to_bm25query(regclass, int[]) overload, and PostgreSQL 18 compatibility. |
v0.2.2 |
bm25_catalog |
bm25vector |
pg_tokenizer |
Added bm25_catalog.enable_prefilter GUC for accurate filtered Top-K BM25 search with WHERE clauses. |
v0.2.1 |
bm25_catalog |
bm25vector |
pg_tokenizer |
Bug fixes for growing/sealed segment transitions and vacuum cleanup. |
v0.2.0 |
bm25_catalog |
bm25vector |
pg_tokenizer |
Added = and <> equality operators on bm25vector and implicit cast CREATE CAST (int[] AS bm25vector) AS IMPLICIT. |
v0.1.1 |
bm25_catalog |
bm25vector |
pg_tokenizer |
Decoupled tokenization into standalone pg_tokenizer extension; changed to_bm25query(regclass, bm25vector) signature. |
v0.1.0 |
bm25_catalog |
bm25vector |
Built-in unicode |
Initial release with bm25vector, bm25query, USING bm25, and Block-WeakAnd Top-K scan. |
Detailed Upgrade Changes
v0.3.0 (sql/vchord_bm25--0.2.2--0.3.0.sql)
- Added page diagnostic function:
- Added
to_bm25query(regclass, int[])convenience overload inmain/late0.3.x.
v0.2.2 (sql/vchord_bm25--0.2.1--0.2.2.sql)
- Added prefiltering support in Block-WeakAnd (
bm25_catalog.enable_prefilterGUC, enabled by default in0.3.0). - Improved MVCC visibility checking during index scans to prevent dead/filtered tuples from polluting the Top-K threshold.
v0.2.0 (sql/vchord_bm25--0.1.1--0.2.0.sql)
- Added
=and<>operators forbm25vector. - Added implicit cast from
int[]tobm25vector(_vchord_bm25_cast_array_to_bm25vector), allowingtokenize(text, name)output (INT[]) to be assigned or passed directly whereverbm25vectoris expected.
v0.1.1 (sql/vchord_bm25--0.1.0--0.1.1.sql)
- Extracted built-in
create_tokenizer/tokenizefunctions into the dedicatedpg_tokenizerextension (tokenizer_catalog), enabling rich text analyzers, Snowball stemmers, stopwords, synonyms, HuggingFace models,jieba, andlindera. - Simplified
to_bm25query(index_oid regclass, query_vector bm25vector)to accept abm25vectordirectly.
Next-Generation Rewrite (main Branch)
- Replaced custom
bm25vectorwith PostgreSQL’s nativetsvector(CREATE OPERATOR CLASS bm25_ops FOR TYPE tsvector USING bm25), allowing users to indexto_tsvector(...)columns directly withUSING bm25. - Added parallel index build (
bm25_parallel_build_main) with external merge sort and constant maintenance memory consumption. - Added configurable BM25 hyperparameters (, ) via
WITH (options = $$ k1 = 1.2, b = 0.75 $$).